How brands can leverage UGC to win AI Search (GEO).
AI Search (GEO) is big business, and the key to winning is a new UGC / Creator Content strategy
Consumers are adopting AI Search at a harrowing pace. And a big piece of that is using it to discovery products. It’s no longer feasible for brands to write off AI search as an ‘evolving space’. It’s time to learn and invest. But the good news is that most of the work has already been done - specifically making sure your site is set up for crawlers and you’re generating UGC.
Here’s your cheatsheet for winning AI Search (GEO/AEO), starting with how to think about it and then how to build a strategy.
The numbers are genuinely hard to believe
ChatGPT is the fastest-growing app in history. It went from roughly 400 million weekly users in early 2025 to 1.2 billion by October 2026. The mobile app crossed 1 billion monthly actives in May 2026 — faster than any app ever has. It now handles somewhere between 2.5 and 2.8 billion messages a day.
The commerce slice is the part marketers should care about: roughly 50 million shopping queries happen inside ChatGPT every single day. That’s only about 2% of ChatGPT’s total volume, which tells you both how big the platform is and how much room shopping has left to grow.
And Google’s grip has loosened. Google’s share of global search-related activity fell from 89% in 2023 to 71% in Q4 2025 (Graphite, via Search Engine Land).
One honest caveat, because it matters: Google isn’t collapsing. Graphite found no decline in search visits. What actually happened is that the total discovery pie grew 26% in 2025 compared with 2024, with AI adding to it. Google is losing share of a bigger market. That’s a real problem for Google, but it’s a different story than “search is dying,” and you should be suspicious of anyone telling you the latter.
Product discovery is moving upstream
Here’s the stat that reframes everything. According to Similarweb’s 2026 AI Brand Visibility Index, 35% of US consumers now start product discovery in an AI tool, versus 13.6% in a search engine.
I’ll be honest: I’m skeptical of the methodology on numbers like this, and you should be too. Estimates for “where do people start a product search” range from about 17% to 45% depending entirely on how the question is worded. NRF and Salesforce put AI product-discovery usage at 45% in early 2026, up from 18% in 2024. Bain finds 44% of online buyers mostly start in an LLM or split between AI and search. Other surveys land closer to one in six.
But the directional finding holds across all of them, and the reason it holds is what matters. LLMs sit upstream of search. Search is where you go when you roughly know what you want. An LLM is where you go when you’re still working out what you need — “what’s a good moisturizer for combination skin,” not “CeraVe PM 3oz.”
The behavioral data backs this up. More than half of AI-referred sessions land directly on a product detail page, versus about 20% for organic search. These people aren’t browsing; they’re arriving on a recommendation. And it shows in the numbers: AI-referred visitors to US retail sites in Adobe’s July 2026 data convert at a 60% higher rate than non-AI traffic and generate 53% more revenue per visit — a complete reversal from a year earlier, when AI traffic converted at roughly half the rate of everything else.
One more piece of the picture, and it’s important: 89.9% of shoppers who use an AI assistant for product research at least sometimes verify its recommendation somewhere else before buying, up from 85.7% in June. AI is a shortlisting layer, not a closing layer. Getting named puts you in the consideration set. It doesn’t close the sale.
A reality check from our own analytics
Before you set a goal of “get cited,” look at what citation is actually worth. We pulled our own Search Console data on a post of ours titled “What Is KOL Marketing?” It ranks #3 for its target query and it is cited in Google’s AI Overview — the outcome every GEO vendor sells.
Over twelve months it earned 2,836 impressions and zero clicks.
Not a handful. Zero. That’s our own first-party data on a page that is, by every scoreboard on the market, winning AI search.
This matches what publishers report at scale — Reuters and The Guardian are among the most-mentioned news outlets in LLMs, and referral traffic from those platforms is under 1% of their total. But our own number is blunter, and it should reframe what you’re optimizing for. Citation is a brand-awareness outcome, not a traffic outcome. Measure it like you’d measure share of voice, not like you’d measure SEO. If you’re buying a tool on the promise of clicks, you are buying the wrong thing.
The related finding, from the same analysis: what actually predicts being cited is rank. In our sample, 44% of #1-ranked results were cited in the AI Overview, versus 12% of results at position #6. Not title formatting, not clever structure. Position.
The good news: you’re probably already doing the baseline
Here’s where a lot of the GEO panic falls apart. The table stakes of AI search are things most brands already have covered.
If you’re running a Google Merchant Center feed, your catalog is already flowing into Google’s ecosystem. If you’re on Shopify, you’re already inside ChatGPT — OpenAI states it plainly: “For merchants on Shopify, product data is already integrated into ChatGPT through Shopify Catalog… No additional work is required from individual merchants.” (OpenAI)
And the two systems overlap more than people realize. 83% of the products in a 43,000-product sample of ChatGPT shopping carousels matched Google Shopping results, and OpenAI accepts Google-compatible feeds for its own merchant program at chatgpt.com/merchants. One clean Merchant Center feed does an enormous amount of work.
This is also why the “GEO is a brand new discipline” pitch should make you suspicious. Two practitioners who have no reason to agree land on the same number. RPA’s Nate King: “It’s 80 to 90% of the same [SEO] tactics and strategies… but that 10 to 20% is actually super critical.” uSERP’s Jeremy Moser is blunter: “80 percent of GEO is good, fundamental SEO. If a GEO service does not openly tell you that, they are selling you snake oil.”
So: the LLMs have your products. They have everyone’s products. Which makes the interesting question a completely different one.
So how does an LLM choose between Coke and Pepsi?
If every product is in the index, what decides which one gets named?
Largely the same way a human decides: by listening to other people. LLMs lean heavily on user-generated content, and they trust it more than they trust what a brand says about itself.
The data on this is unambiguous. Ahrefs tracked every domain Google AI Overviews cited across more than 3 million US queries (September 2026):
| Rank | Domain | Mention share |
|---|---|---|
| 1 | YouTube | 22.9% |
| 2 | 18.5% | |
| 3 | 10.1% | |
| 4 | 8.8% |
Mention share = each domain’s citations as a percentage of the summed citations of the top 50 sources — not of all citations on the web. Source: Ahrefs Brand Radar, 3M+ US queries, all topics, September 2026.
Two caveats that matter more than the numbers. First, that denominator: because the long tail is excluded, these percentages run higher than a true share-of-everything would. Second, and more important — these are all-topics figures, and citation sources are heavily category-dependent. We ran our own spot check across 50 marketing-topic queries and saw Reddit at just 5.5% and Facebook at 0.4%, a fraction of the all-topics numbers. Marketing queries pull from marketing publications; consumer product queries pull from Reddit and YouTube. Which is the whole point: before you spend a dollar on AI visibility, find out which sources your category actually cites. The aggregate leaderboard is not your leaderboard.
Look at that list. The top 4 capture about 60% of the share, and almost all of them are places where regular people talk — not publishers, not brands, and conspicuously not your website.
It holds at the category level too. Novi analyzed 10.7 million ChatGPT citations across 98,000+ sites for beauty queries and found Reddit first by a substantial margin, followed by Who What Wear, Wikipedia, Sephora, and Allure. A separate study of 28 retail and CPG brands put it bluntly: review sites, editorial, aggregators, and Amazon “consistently captured the citation slots that brand domains missed.”
Viral Nation CEO Joe Gagliese describes the mechanic well: “The machine is going towards the most accessible public information and the most authentic to get closer to an answer. That’s not coming from the brand themselves.”
This doesn’t mean your site is worthless. It means it’s authoritative for a specific category of question. Your domain is the best source on what your product is — ingredients, specs, sizing, certifications, what’s in the box. Neutrogena and La Roche-Posay both place in the skin care citation top 10, and both are ingredient-led brands with substantiated claims. Novi found products carrying verified certifications and trust indicators get recommended more often. As their CEO Kimberly Shenk put it: “Marketing copy alone is not enough.”
But on the question of whether your product is good? You’re structurally disqualified. Nobody — human or model — takes a brand’s word for that.
The problem: your best UGC is somewhere LLMs can’t reach
Here’s the trap. For most consumer brands, the overwhelming majority of authentic product conversation lives on Instagram and TikTok. That’s where your creators post, where customers tag you, where the actual cultural conversation about your product happens.
And those are exactly the platforms LLMs have the hardest time reading. Instagram and TikTok have gotten more hostile to automated access through 2026 — login walls, GraphQL obfuscation, aggressive IP flagging. They’re walled gardens by design.
You can see the consequence right in the citation data. Instagram sits at 5.6% and TikTok at 3.3% — not zero, since Google indexes some of it, but a fraction of their share of actual product conversation. Meanwhile Facebook pulls 10.1% and Quora pulls 4.7%.
Think about how strange that is. Quora. Facebook. These are not where your brand’s best content lives, and they’re not where your customers are having their most useful conversations about you. They’re just readable.
That’s the whole distortion. LLMs over-index on platforms that are machine-accessible, not platforms that are culturally important. Your best advocacy is invisible, and a ten-year-old Quora thread is not.
YouTube proves the point
The cleanest evidence that this is an accessibility problem rather than a quality problem is YouTube’s rise to the #1 cited domain.
YouTube didn’t become more trustworthy or more popular. It became readable. As Adweek reported, YouTube had previously lagged other user-generated sources “because of the difficulty large-language models have in pulling information from videos, but transcripts, explainers, and other information associated with videos have allowed the video platform to flourish as a source that machines can easily read.”
A text layer got added over video, and citation share followed. That’s the entire lesson in one case study: the content was always valuable; it just needed to be in a form a machine could ingest.
Later CEO Scott Sutton names the same failure mode from the brand side: “If I have 300,000 TikTokkers making content about my new soap, that’s not going to get picked up via AEO because it’s not in the right spot to get ingested into the AEO engine.”
Volume of advocacy is not the constraint. Format and location are.
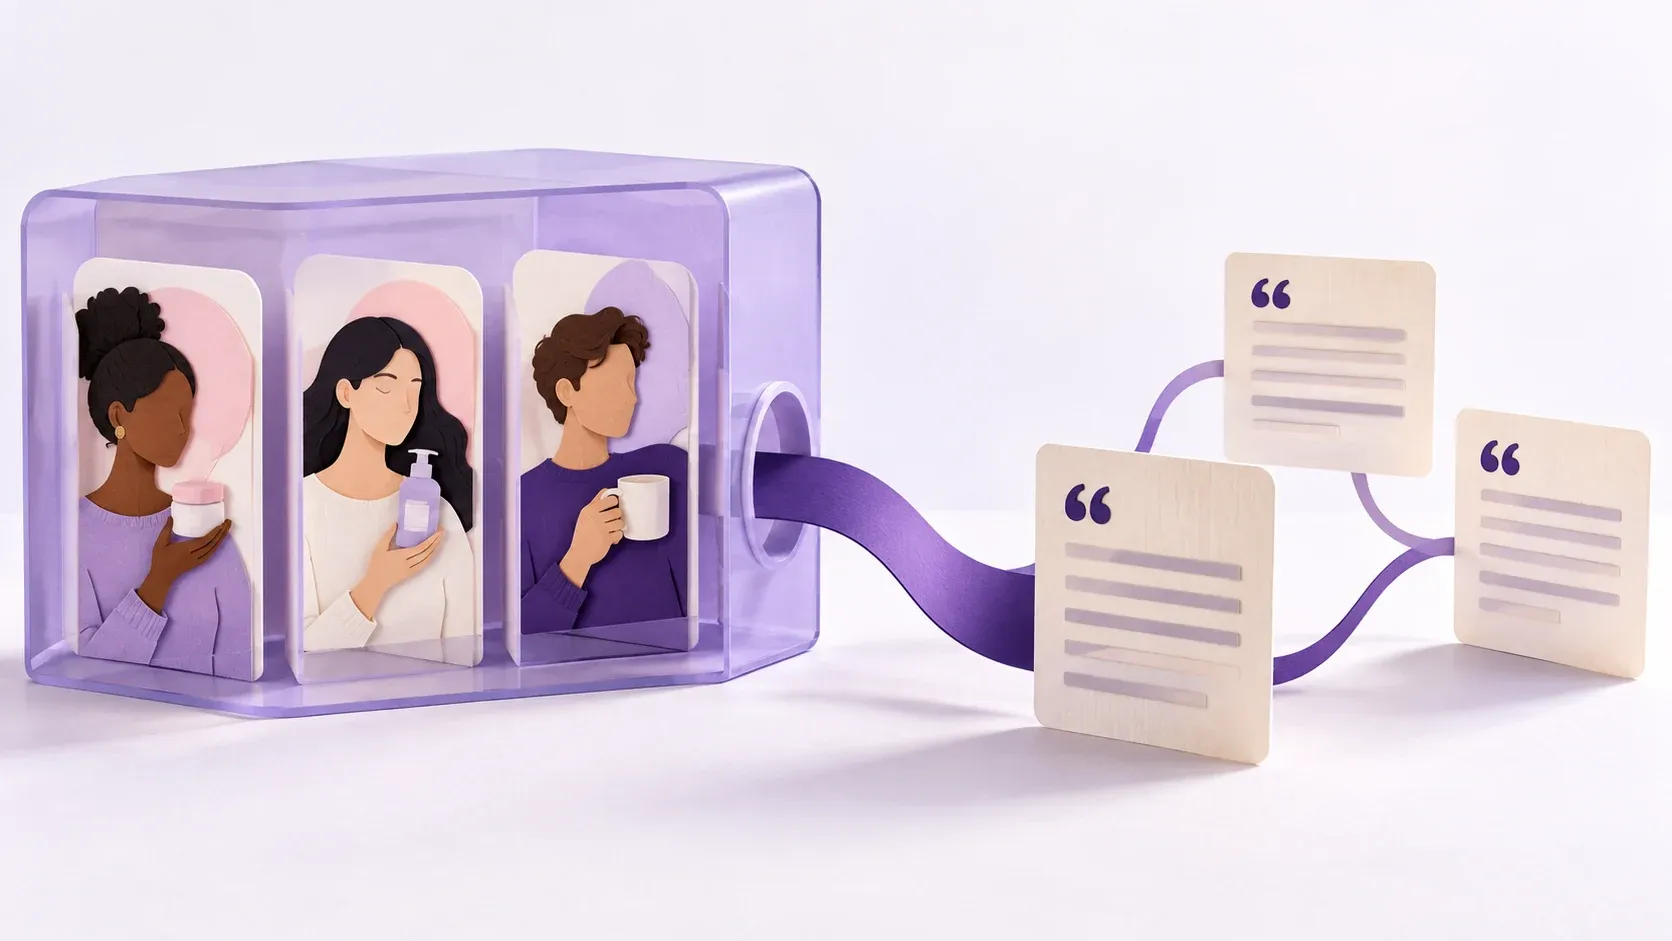
Conceptual illustration: creator content moving from a closed feed to readable documents.
What the research says actually moves citations
Most GEO advice is assertion. There are two controlled studies worth knowing, and the newer one is the better guide.
“What Gets Cited: Competitive GEO in AI Answer Engines” (Vishwakarma, Kumar & Jamidar, SIGIR ‘26, arXiv:2605.25517) ran 252,000 trials across six LLMs, testing 18 content factors head-to-head in a controlled retrieval setup with brands anonymized and source order counterbalanced. They report a clear hierarchy. These odds ratios measure which of two sources injected into model context receives the first citation, not live search rankings:
| Factor | Effect (odds ratio range across 6 models) |
|---|---|
| On-topic vs. off-topic | 221 to >10,000 |
| Explicit price present | 6.26 to >10,000 |
| Recent vs. old timestamp | 14.4 to >10,000 |
| Source position #1 vs #2 in model context | 1,795 to >10,000 |
| Specs present vs. missing | 8.63 to >10,000 |
| Deep vs. shallow coverage | 3.98 to >10,000 |
| Confident vs. hedged language | 2.67 to 754 |
| Claims backed by evidence | 2.09 to >10,000 |
| Query terms present in content | 5.99 to 40.0 |
| Content structure / formatting | 0.78 to 1.68 — small or mixed effects |
Two things to take from this.
Price and recency are enormously underrated. Most brands publish product content with no explicit price and no visible date. Both show up here as near-decisive. If you fix one thing this week, add prices and timestamps.
Formatting barely matters. The authors are direct: “formatting changes showed minimal return and can be deprioritized.” So the whole industry of restructuring your page into tidier sections to please the robots is, on this evidence, largely wasted effort. What does matter is having the query’s actual terms in your content, saying things confidently, backing claims with evidence, and being comprehensive.
One fair criticism: the paper’s own prose claims all four gatekeepers cleared OR > 100 on every model, but its table shows price and timestamp falling well below that on two models. The effects are real and significant; the “unanimous above 100” framing overstates them. Worth knowing if you cite it.
The earlier Princeton study (arXiv:2311.09735, KDD 2024) points the same direction on content: citing sources, adding statistics, and quoting named experts lifted visibility by up to 30–40% in its benchmark, while keyword stuffing did nothing at all.
Neither study tested headlines or titles. If someone tells you a particular title format wins AI citations, ask what they’re basing it on.
What this actually means for your job
If you own digital, SEO, or GEO at a consumer brand, the highest-leverage work in front of you is this: get your best creator and customer content onto surfaces LLMs can actually read.
This is already becoming a formal deliverable. Agencies have started building it into briefs — Trevant audits which creators and content types drive the most LLM citations and then tracks citations live; Crispin targets creators already being cited in LLM results; Zoom ran a campaign specifically to build authority that models would pick up. Trevant’s Kristina Coughlin: “We are getting that in nearly every pitch we’re doing now.” (Digiday)
Practically, the work breaks into a few pieces:
- Audit what’s already being cited. Find which of your existing creator content, reviews, and third-party mentions LLMs are currently pulling. Most brands have never looked.
- Move the best material to readable surfaces. Long-form video with clean transcripts. Published, indexable written content. Review and Q&A data that can be structured.
- Use the structured channels you already have. OpenAI’s current product feed spec includes fields for
review_countandstar_rating— a direct, merchant-controlled path to put social proof in front of ChatGPT. Raw review entries and Q&A lists are excluded from this feed contract; publish those on readable product pages. - Fix your facts on your own domain. Ingredients, testing, certifications, specs, sizing — structured and machine-readable. This is the one place you are the authority.
- Add explicit prices and visible dates to everything. The cheapest win on this list, and the one almost nobody does. Both rank as near-decisive factors in the SIGIR data.
- Find out which sources your category actually cites before you spend anything. Beauty leans Reddit; B2B leans LinkedIn; marketing queries lean trade publications. The aggregate leaderboard is not your leaderboard.
- Don’t fake it. Reddit removed 25,000 spammy posts and comments a day in Q1 2026 and screens accounts from creation. The WSJ has reported that Redditors noticed brands’ sudden interest and are not charmed. Synthetic seeding is a short-term tactic with long-term downside.
- Measure it as awareness, not traffic. See our own zero-click data above. Track citation share and sentiment; do not promise your CFO clicks.
There are manual ways to do all of this, and some brands have figured them out. There are also tools for it now — including ours.
But the strategic point stands regardless of how you execute it: the LLMs already know your products. What they don’t have is a reason to pick yours. That reason lives in what other people say about you — and right now, most of it is sitting somewhere the machines can’t see.
Getting it where they can is the most scalable advantage available in AI search today.
Sourcing note: the two peer-reviewed studies (SIGIR ‘26 and KDD 2024), plus Adobe Analytics, Ahrefs, Graphite, Similarweb, NRF/Salesforce, Bain, and OpenAI’s own documentation, are the most methodologically solid figures here. Novi and Conductor data come from companies selling into this category. Our own Search Console figures are first-party. Where estimates conflict — AI product-discovery adoption ranges from roughly 17% to 45% depending on survey wording — ranges are given rather than a single number. Citation-share percentages are all-topics aggregates and vary substantially by category; treat them as directional for your vertical, not predictive.
Turn creators into your top revenue channel.
Agents, storefronts, and performance programs in one platform — in production for the world's most forward DTC brands.
More from the blog.
All posts → Strategy
The influencer agency is dead. Long live the influencer agency.
AI now automates most of what influencer and affiliate agencies sell. A service-by-service breakdown of what's at risk — and which agencies win.
Read more → Strategy
The agentic future of influencer marketing: what humans own
Agentic influencer marketing is here. A framework for what to delegate to AI agents — and what to keep in human hands.
Read more → Strategy
Social Shopping: The Future of E-commerce Is Here
The line between social media and e-commerce has blurred into social shopping, where consumers discover, research, and buy in one place.
Read more →